

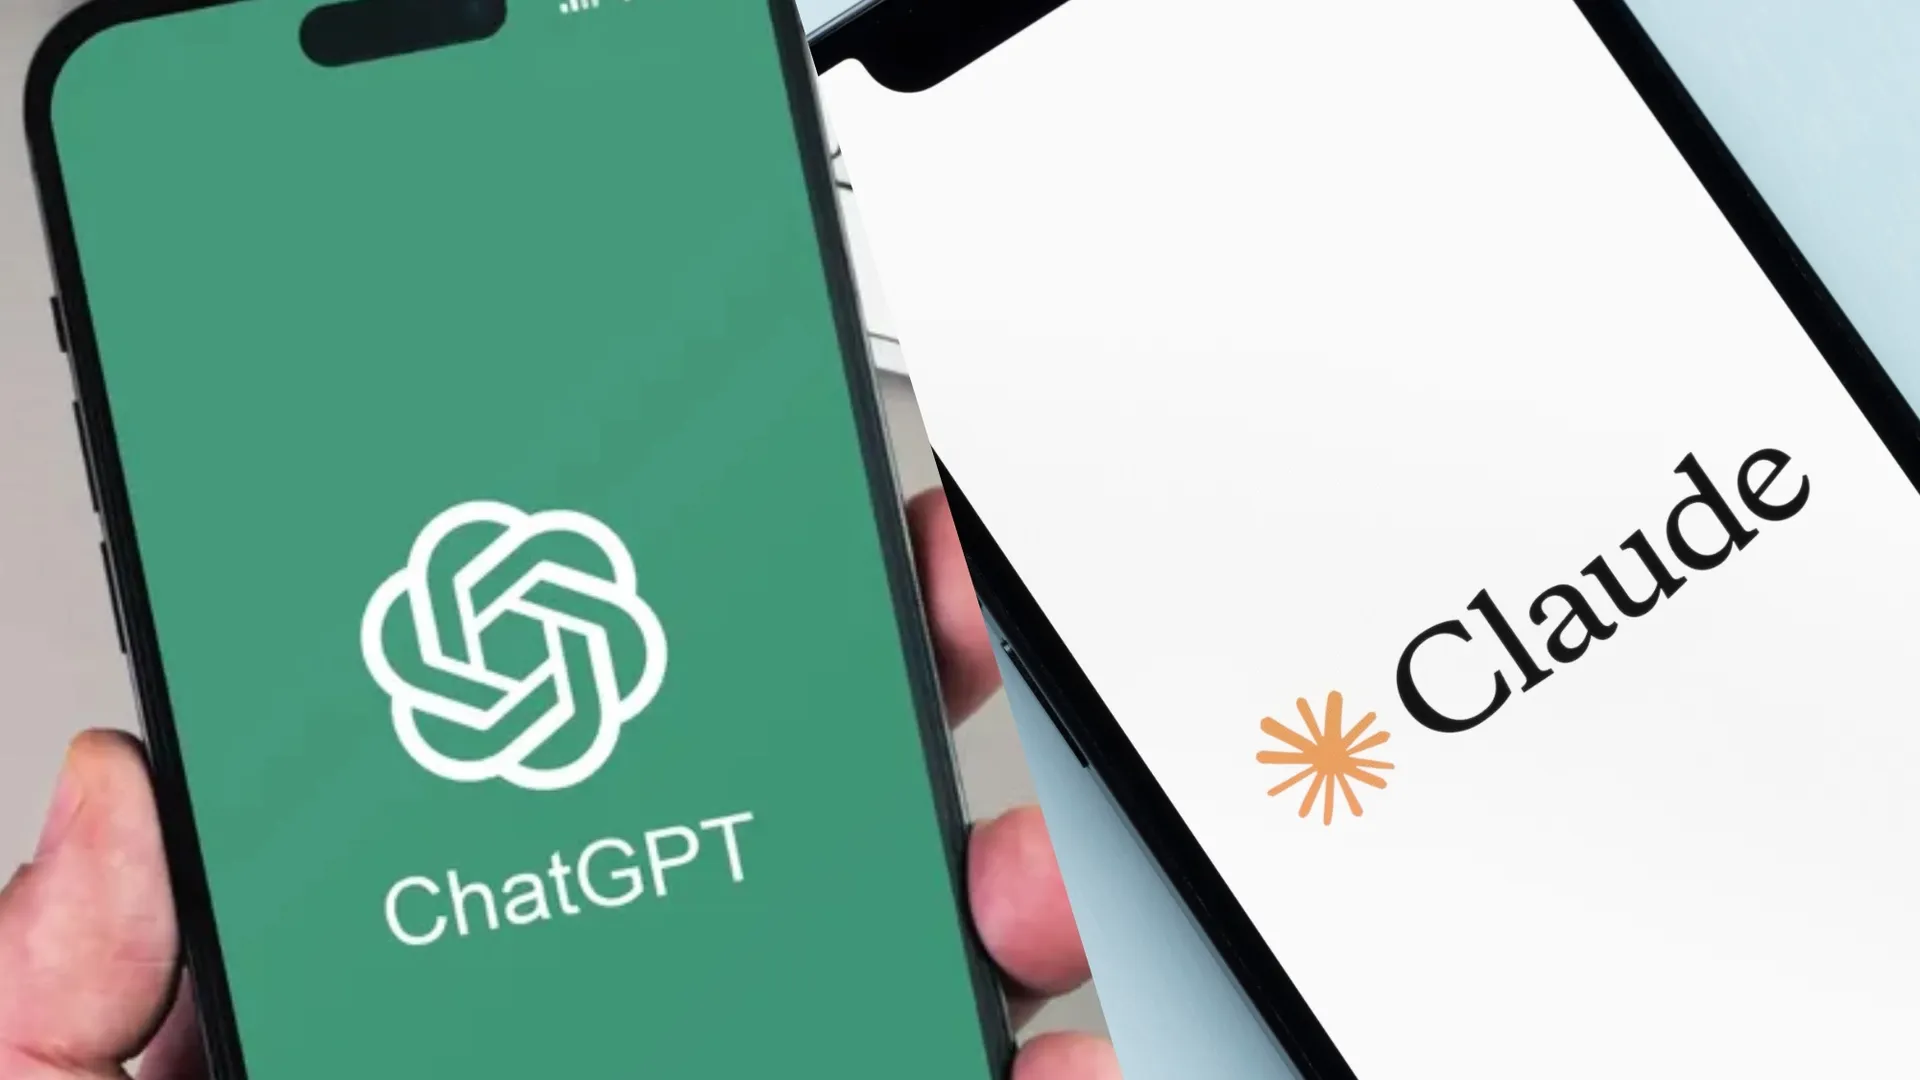
OpenAI and Anthropic both released new flagship AI models this month, ChatGPT-6 and Claude Opus 5.5. Both are ridiculously capable to the point that they do so much more than what most users prompt them to.
OpenAI's GPT-6 family builds on GPT-6 Astra, the company's most impressive model yet, with major gains in areas including reasoning, professional work, coding, browsing and computer use. The newer GPT-6 Sol brings much of that intelligence into the version designed for everyday work, with OpenAI positioning it as a faster and more affordable reasoning model.
Claude Opus 5.5 comes at the problem from a slightly different direction. Anthropic describes it as a model built for long-running agentic and knowledge work, with adaptive thinking that determines how much effort a request needs. It has a 1 million-token context window, can produce up to 128,000 output tokens and, according to Anthropic, reaches roughly the same performance as its higher-end Claude Fable 5.1 on most tasks while costing 40% less to run than the previous Opus. Anthropic has also specifically highlighted improvements to how naturally the model communicates and follows writing instructions.
Those differences sound impressive, but they don't necessarily tell you which chatbot you'd rather have helping you in real life.
So I gave ChatGPT-6 and Claude Opus 5.5 the exact same five prompts. The result wasn't the clean sweep I expected. Here's what happened when I put them through every day prompts.
1. Messy real-world planning — constraints + judgment

Prompt: I have $150 to plan a birthday party for 10 kids ages 8–11. It needs to last three hours, work indoors if it rains, include food, and keep screen time to a minimum. Two kids are vegetarian and one has a peanut allergy. Create the full plan, including a budget, timeline, activities and backup plan. Do not go over $150.
ChatGPT offered clear conceptual framing by giving the event an immediate identity and direction. Budgeting $36 for 3 delivery cheese pizzas is practically easier for a parent hosting 10 kids than managing DIY mini-pizzas in a standard home kitchen. It also recognized the need for an "Emergency/price buffer" at the end.
Claude was smart for being proactive about allergies and dietary protocols. It also addressed cross-contamination of bakery cakes and boxed mixes. It also did double-duty budgeting by spending 14 on canvas tote bags and $12 on fabric markers serves as both an arrival craft activity and the take-home party favor, saving money and cutting down on cheap plastic filler. It also offered an actionable, timed schedule and operational troubleshooting.
Winner: Claude wins because it delivered a turnkey, host-ready plan with genuine safety diligence, whereas ChatGPT produced a fragmented grocery list.
2. Writing — make AI sound human

Prompt: Rewrite this boring announcement so it sounds like something a real person would actually want to read. Keep every factual detail, don't use em dashes, avoid clichés, and don't use the words “exciting,” “revolutionary,” “game-changing” or “seamless.”
“Our company is introducing a new AI-powered calendar feature that automatically identifies scheduling conflicts, recommends meeting times and creates summaries after meetings. The feature launches October 15 and will be available to all customers at no additional cost.”
ChatGPT offered a punchy one-liner that draws the reader in and it also avoided AI styles and retained every factual detail. The paragraph breaks make it easy to scan quickly.
Claude reframed the bullet points into concrete human benefits and reframed the details around actual workplace relief.
Winner: Claude wins because it understood that a "human" rewrite requires rethinking how to explain the value of the features, rather than just shifting a few verbs in the original text.
3. Reasoning — the answer isn't obvious

Prompt: A family is choosing between two vacation rentals. Rental A costs $1,850 and is a 10-minute walk from the beach. Rental B costs $1,500 but requires a 25-minute drive to the beach and $35 per day for parking. They're staying seven days and expect to visit the beach twice a day. They have three kids. Which should they choose? Don't just calculate the cost. Identify the factors that could change your recommendation and tell me what additional information would matter most.
ChatGPT provided the single best counter-perspective on kids' ages. It also smartly pointed out that a "10-minute walk" varies wildly depending on infrastructure (boardwalk vs. crossing a four-lane highway or traversing sand dunes). The chatbot specifically noted that Rental A allows parents to split up (e.g., one parent takes a tired child back while the other stays at the beach with the other two).
Claude actually did the mileage math, proving that the financial savings of Rental B is effectively a negligible $55–$65 total for the entire week. Claude also made an astute psychological point: loading/unloading three kids into car seats four times a day means the family will likely abandon the second daily beach trip entirely. It also correctly flagged vacation rental platforms' dirty secret: base rates don't reflect cleaning fees, service fees, or occupancy taxes, which could easily flip the $105 difference on their own.
Winner: Claude wins by a hair. Although ChatGPT had the best individual point (realizing that walking with heavy beach gear and young kids can actually be more grueling than driving), Claude won overall because its financial breakdown was thorough down to the gallon, it anticipated hidden fees, and its observation that the commute would cause the family to cancel their planned outings was spot-on.
4. Option overload — find what's important

Prompt: A city has $10 million to spend and three options:
A) Build a new public library expected to serve 200,000 visits per year for at least 30 years.
B) Give every household a one-time $500 payment.
C) Upgrade aging water infrastructure, which residents won't notice unless something goes wrong.
The city can only choose one. Choose the option you think is best. Explain your reasoning, identify the strongest argument against your choice, and explain what additional piece of information would be most likely to change your answer. Do not hedge by saying all three are good options.
ChatGPT followed all instructions cleanly and delivered an easy-to-read defense of option C. It also cleanly defined the engineering assessment threshold.
Claude framed the choice it made through municipal incentives and recognized that funding what electoral politics ignores is the core function of city management.
Winner: Claude wins for answering significantly better. The chatbot seemed liked it had experience in public-finance administration whereas ChatGPT’s response felt more standard and surface-level.
5 The killer test — vague request + initiative

Prompt: My life feels disorganized. I have three kids, a full-time job, household responsibilities and about 30 minutes every evening to get things under control. Build me a system I could realistically maintain. Don't give me generic productivity advice. Make reasonable assumptions where necessary, tell me what you're assuming, and give me something I can start tonight.
ChatGPT offered simple ways to prevent burnout and included instructions that were broken down into steps so the user doesn’t have to plan or try to guess where to start.
Claude addressed the mental load, which is a sharp, accurate insight into why disorganization happens. It also mentioned a useful tip of delegating when possible chores while recognizing that one parent cannot be the sole operational engine for a family of five.
Winner: ChatGPT wins because its cognitive framework is much more protective of an exhausted parent’s mental bandwidth. Claude gave a good domestic organizing routine; ChatGPT gave a decision-making filter that actually keeps work, family, and life from cannibalizing each other.
Overall winner: Claude
After five tests, Claude Opus 5.5 came out ahead in four. But what surprised me was how consistently the same difference between these models showed up across completely unrelated tasks. Claude tends to keep digging.
When I asked it to plan a birthday party, it thought about cross-contamination and found ways for one purchase to serve two purposes. When I gave it the vacation rental problem, it calculated costs I hadn't explicitly asked for and considered whether the inconvenience of driving would actually change the family's behavior. Even when choosing how a city should spend $10 million, it looked beyond the obvious pros and cons to think about why governments make these decisions in the first place.
That's where Opus 5.5 felt strongest. ChatGPT-6 was generally more streamlined, which is very much still on-brand for ChatGPT. Regardless of the model, ChatGPT always seems to be the less "fluffy" of the two models, with a response that gets to the point faster. That also means that, at times, its answers didn't go quite as deep as Claude's. However, that approach became an advantage in my final test.
Follow Tom's Guide on Google News and add us as a preferred source to get our up-to-date news, analysis, and reviews in your feeds. Subscribe to Tom's Guide on YouTube and follow us on TikTok.
More from Tom's Guide